

Evaluation has always been a critical point in education, but in recent years it has become a real concern.
With the rise of remote and hybrid learning, and with tools like generative AI accessible to any student, the question is no longer whether they can cheat, but how to design assessments that remain useful, fair, and trustworthy.
The simplest solution might lie in technology: more monitoring through digital tools.
But experience and research in educational assessment also invite us to look in another direction: reliability can also be enhanced through design. A reliable and secure exam stems from a comprehensive approach that combines:
- Solid pedagogical design (what you ask and how you ask it).
- Smart technical configuration (how you present and limit the exam).
- Risk-proportional supervision (proctoring when appropriate, with clear criteria).
- Continuous review and improvement (analysis of results and adjustments).
- A culture of integrity (rules, communication, and institutional consistency).
In this post, you will find practical strategies – applicable in LMS like Moodle, Canvas, Blackboard, or others – to create exams that better reflect what the student knows and can do, with less room for fraud and more room for real learning.

Before “preventing cheating”: what makes an exam truly reliable
When we talk about “reliable” exams, many people think only of preventing cheating.
But an exam can be secure yet still be poorly designed (for example, if it measures irrelevant things or unfairly penalizes certain students). That’s why it’s worth separating two key ideas:
- Reliability: consistency. If the student had to take an equivalent test under similar conditions, would they obtain a similar result?
- Validity: relevance. Does the test measure the learning objectives, or does it measure something else (literal memory, speed, guessing ability, stress tolerance)?
A secure exam that drastically reduces time or forces students to answer without reviewing might “block” fraud… but also introduces noise (stress, errors due to rush, penalization of students with specific needs).
The goal is not just to identify cheating: it is to obtain credible evidence of learning.
Quantity and quality of questions: more is not always better, but less is often worse
In objective tests (especially multiple-choice), having few questions increases the influence of chance. If a significant part of the grade depends on 8 or 10 items, a misunderstanding or a momentary distraction can sink the result, and a lucky guess can inflate it.
However, the solution is not “to include 200 questions.” The key is:
- Adequate coverage of the syllabus: sufficient representation of the learning outcomes.
- Quality of wording: ambiguous, poorly formulated, or “trick” questions reduce reliability and validity.
- Balance of difficulty: if everything is too easy or too difficult, the test discriminates poorly.
A practical tip: create a table of specifications (test blueprint). It is a simple document where you cross topics/competencies with cognitive levels (e.g., remember–comprehend–apply–analyze–evaluate). This avoids “whimsical” exams and improves consistency.
Discriminatory power: the ideal question separates levels of domain
An item adds value if it distinguishes between students with high domain and students with low domain. In classical evaluation, we talk about:
- Difficulty index (what percentage gets it right).
- Discrimination index (how well it separates those who know from those who don’t).
Two warning signs:
- If almost everyone gets it right: perhaps the question is too obvious or trivial.
- If almost everyone gets it wrong: perhaps the content was not taught well, the question is confusing, or the difficulty is excessive.
Even if you don’t calculate formal statistical indices, you can do something very useful: review patterns after each call. If a question “crushes” good students or generates consistent complaints, it deserves review.

Correction method: consistency, rubrics, and criteria
In open questions or assignments, reliability depends on the correction. Two teachers can read the same text and assign different grades if:
- there is no clear rubric,
- the rubric is not anchored in evidence,
- or the workload causes fatigue and variability.
If you are going to include open questions (highly recommended to reduce cheating), compensate with:
- rubrics with concrete descriptors,
- examples of “excellent / adequate / insufficient” answers,
- and, if possible, double review of a sample or moderation among teachers.
Context matters: time, environment, and accessibility
In the digital world, the environment can be very unequal:
- noise at home,
- bad connection,
- shared equipment,
- time differences,
- stress or fatigue.
This affects the results even if the knowledge is the same. If you seek reliability, you need reasonably stable conditions or, at least, clear rules and alternatives when there are justified incidents.
Question design: the most effective barrier against fraud
Here is the central idea: if a question can be answered by copying and pasting from the internet in 30 seconds, the problem is not (only) supervision; it is the design.
Cheating is often worthwhile when:
- the answer is “somewhere”
, - isolated data recall is enough,
- the exam is the same year after year,
- or all students have exactly the same questions.
If you want to realistically reduce cheating, you need fraud to be not very useful and for the answer to require comprehension, judgment, and elaboration.
Shift the focus: from memorization to application (without demonizing memory)
Memorization is not “bad,” but it is easy to externalize: search engine, notes, AI, classmates. If you evaluate only literal recall, you are evaluating what is most automatable today.
Quick comparison:
- Fragile question: “In what year was the Treaty of Versailles signed?”
- Robust question: “Based on two economic consequences of the Treaty of Versailles, explain how it could have contributed to the social climate that favored the rise of nationalism in Germany. Justify with causal relationships (not just enumerations).”
The second forces students to connect concepts, argue, and show comprehension. Copying a loose phrase is no longer enough.
Design for higher-order skills
Without turning an exam into a thesis, you can raise its cognitive level with simple techniques:
- Argument analysis: present a statement with premises and ask to identify assumptions, fallacies, or gaps.
- Decisions with imperfect data: offer incomplete or even contradictory information, and ask to justify the decision.
- Transfer: the same concept in a new context.
- Synthesis: integrate content from various units into one answer.
A very useful trick: add a second layer to the question. For example:
- choose the correct option, and
- justify in 3–5 lines why the other options are incorrect.
This reduces “lucky guessing” and makes it much more difficult to copy without comprehending.
Questions resistant to Google (and AI): specificity, context, and evidence
In 2026, the challenge is no longer just Google. AI can generate plausible explanations in seconds. To increase resistance:
- Contextualize with a specific case (from the course, from a fictitious company, from a concrete dataset).
- Ask for evidence: “cite the data from chart X”, “justify with the calculation result”, “refer to two concepts seen in unit 3”.
- Demand process: “show steps”, “explain why you rule out alternative A”.
- Introduce variation: different parameters per student (numbers, scenarios, variables).
Examples by area:
- Mathematics/Statistics: “With the data (table) calculate the regression and explain what would happen if you eliminate the outlier. The result is not enough; interpret.”
- Programming: “Given this code with a bug, explain the failure, propose a solution, and justify its complexity.”
- Health: “Given this patient (signs, history, medication), prioritize differential diagnoses and justify the choice of tests.”
- Law: “With this jurisprudence and this assumption, argue for and against before concluding.”
The key is that the answer must be a product of reasoning, not a definition.
Do you want to stay on top of the latest trends in eLearning, EdTech, and Human Resources?
Fill out the form to receive our weekly newsletter with industry insights from our experts.
Avoid predictable patterns (and also avoid “trick questions”)
There are two frequent errors:
- Exams that repeat format and style so stably that students can “study the pattern” more than the content.
- Exams with tricky wording that punish the honest student and not necessarily the one who cheats.
The optimal approach: vary formats intentionally:
- well-constructed multiple-choice (with plausible distractors),
- short application questions,
- a longer case study,
- a reflection or justification question.
And, when using multiple selection, take care of the basics:
- clear prompts,
- a single best answer,
- plausible distractors (not absurd),
- avoiding grammatical clues (“all of the above” is usually a bad idea).
Technical configuration: randomization, item banks, and smart limits
Once the pedagogical design is right, technology multiplies your ability to protect the assessment. Here you should think like an architect: you don’t need a single gigantic wall; you need several medium-sized barriers.
Randomization at various levels (and why it works)
Randomization reduces the value of “passing answers” in real-time.
- Question order: each student sees a different sequence.
- Option order (in multiple-choice): the correct one is not always B.
- Question banks: a sample is drawn randomly from a large set.
This not only makes cheating difficult: it also reduces leaks. If someone tries to memorize questions to pass them on to the next cohort, the success rate decreases if the bank is large and renewed.
Practical advice: if today you have 40 fixed questions, set a realistic goal: convert them into a bank of 120–200 items in one or two academic years, growing through iterations.
Parameterized questions (when it makes sense)
In quantitative subjects, a very powerful strategy is to create questions with variables that change:
- you change the numbers,
- you change initial conditions,
- you change data in a table.
If you also ask for interpretation, “passing the result” is not enough; the student has to understand the procedure.
Navigation restrictions: one by one, no backtracking… with judgment
Some configurations reduce coordination among students:
- Show one question per screen.
- Prevent backtracking (once submitted, it is closed).
- Block copy/paste (when applicable).
But beware: these restrictions increase pressure and can affect students with specific needs or anxiety. Use them when the exam is high-stakes and compensate with:
- clear instructions,
- prior practice with a “demo exam,”
- and contingency policies (what happens if the connection drops).
Time limits: less “time to search,” more evidence of fluency
Time is a double-edged sword. Well-calibrated, it reduces the student “Googling” every item. Poorly calibrated, it becomes unfair.
A general (very general) guideline for multiple-choice:
- simple questions: 45–60 s,
- medium questions: 75–90 s,
- questions with a chart/case: 2–3 min.
Rather than imposing an aggressive timer:
- Set a reasonable overall time,
- Implement a design that requires thinking (if there is justification required, searching is less effective).
Remember that if you have students who require accommodations (dyslexia, ADHD, etc.), the LMS must allow extended time without breaking equity.
Authentic assessment: when “cheating” stops making sense
If your goal is to measure real competence (not just retention), authentic assessment is your ally. It consists of tasks that resemble what a competent person would do in real life: analyze, decide, create, argue, execute.
Authentic formats that work especially well in digital formats
- Applied projects: reports, prototypes, intervention plans, communication pieces, scripts, data analysis.
- Case studies: diagnosis + alternatives + justification.
- Simulations and role-play: with real-time or staged decisions.
- Portfolios: cumulative evidence (reduces the “all or nothing” of the final exam).
- Brief oral defense (or video): 3–7 minutes explaining decisions and answering questions.
This last point is key: the short defense is a powerful anti-cheating tool. If a student submitted a perfect paper but cannot explain it coherently out loud, you have a clear signal.
How to make authentic work assessable
The main fear of teachers is grading time. It can be managed with:
- well-designed rubrics (less improvisation),
- Milestone submissions (you reduce “final copy and paste”),
- feedback through templates,
- and, if the group is large, combine:
- an automatic part (short concept test),
- an authentic part (case/project).
A very effective combination is the “mixed exam” model:
- 60–70%: objective test (robust, random, with a large bank)
- 30–40%: applied case or brief defense
Supervision and proctoring: perimeter protection
There are contexts where remote proctoring makes sense: university exams, certifications, access to clinical practices, professional qualifications, high-stakes exams, or when you must comply with external standards.
Transparency also matters: the student must know what is monitored, why, and how their data is protected (especially in environments with GDPR or other regulations).
What a complete proctoring system does
Comprehensive proctoring usually covers:
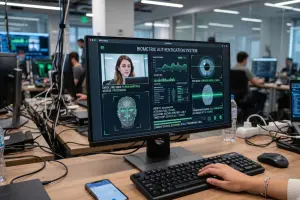
- User authentication (document + biometrics/face).
- Environment monitoring (is there another person?, notes?, smartphone?).
- Supervision of what happens on the device (tabs, apps, shortcuts, window changes).
- Evidence logging (video/audio/events with timestamps).
- Alerts and reports for human review (not everything should be automatic).
Example: SMOWL as an integrated solution (and why it’s relevant in 2025–2026)
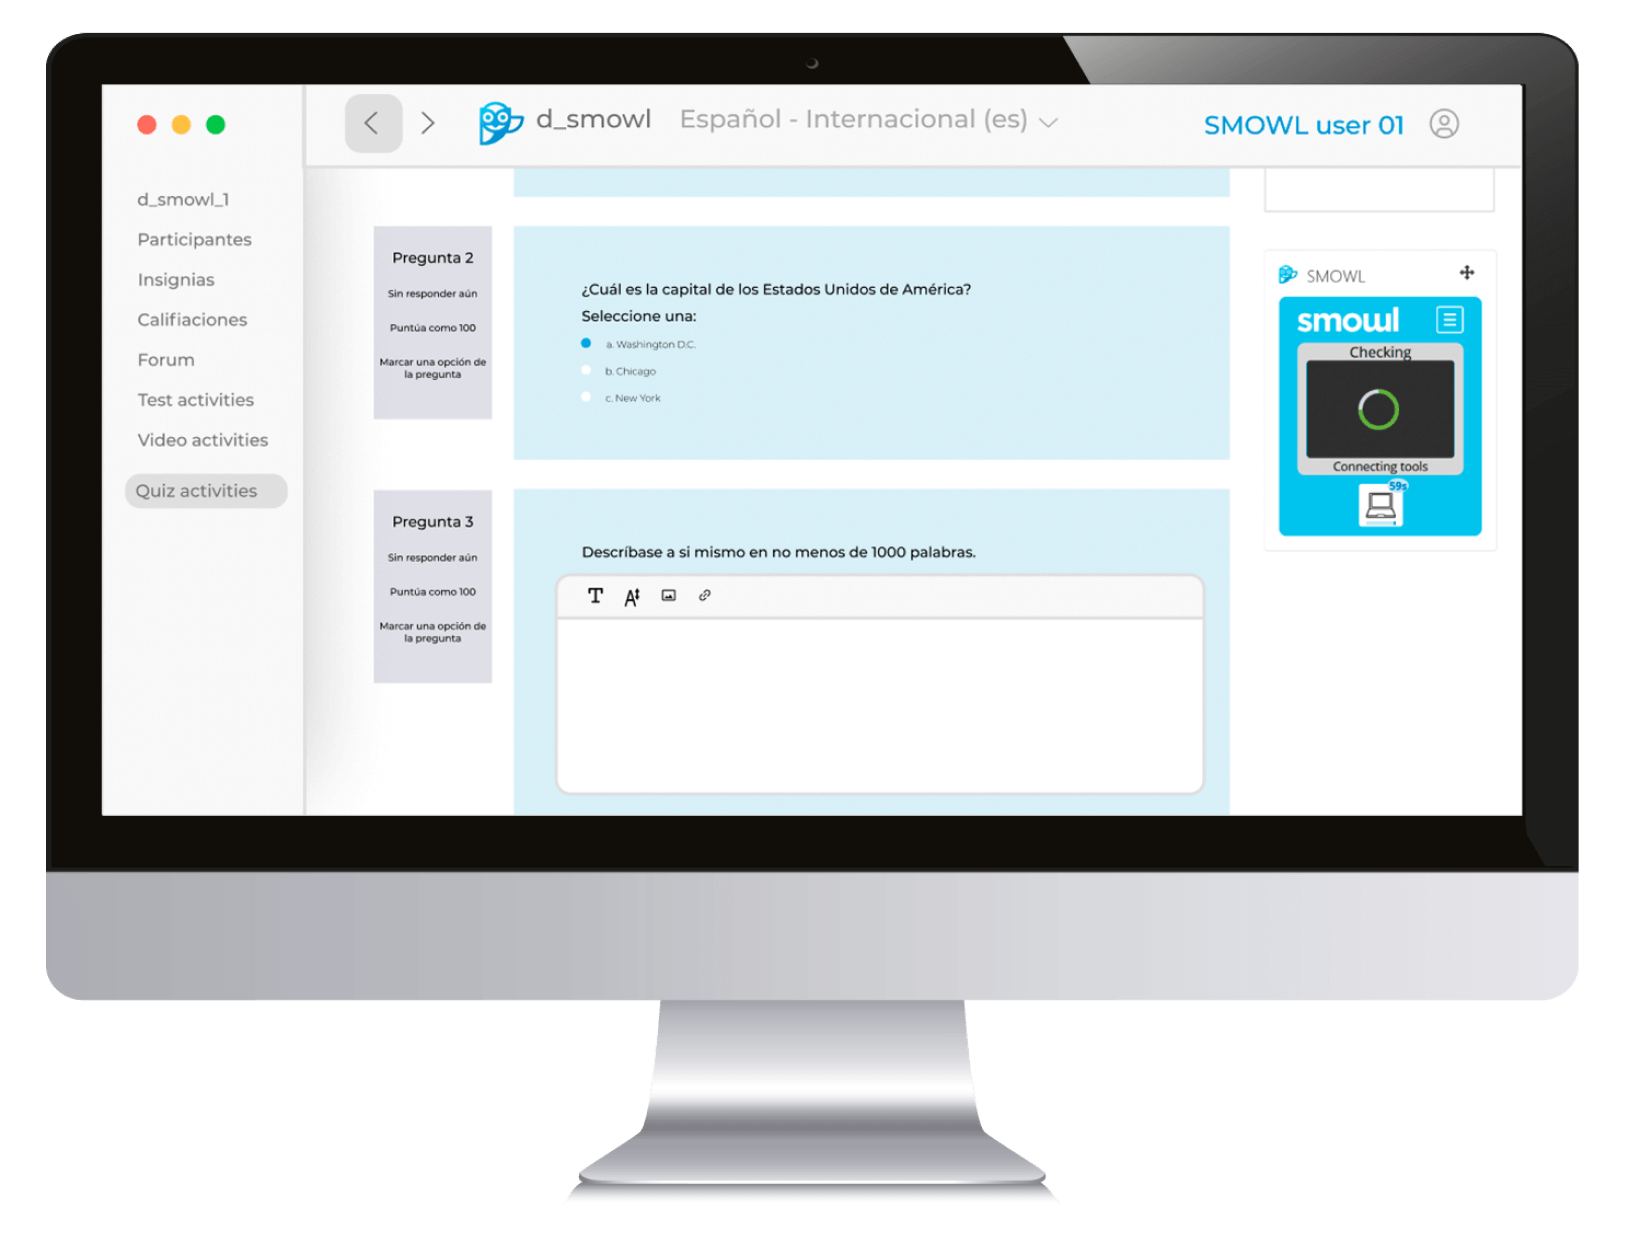
Within the proctoring landscape, SMOWL is an example of a multi-module approach aimed at reducing fraud in digital exams. Among its most known features are:
- Continuous biometric authentication: not only at the beginning; it authenticates users during the session through facial recognition.
- Computer monitoring (SMOWL CM): detects open applications, attempts to use virtual machines, and, especially relevant today, opening of generative AI tools (e.g., ChatGPT, Copilot, Gemini) if the exam policy prohibits them.
- Browser Lock: limits access to unauthorized websites or tabs.
- Enviro Scan: use of a second camera to scan the environment and detect unauthorized devices.
- Audio and video recording with tagged events.
An important point in modern proctoring is differentiating incidents: an internet outage is not the same as a deliberate attempt to hide the camera or repeatedly change tabs. Systems that record events with context facilitate fairer decisions.
Culture of integrity: the most underestimated human factor
You can have the best question bank, the best LMS, and the most sophisticated proctoring solution. If the institutional culture conveys that “the only thing that matters is the grade,” the incentive to cheat will remain alive.
Integrity is built with:
- clarity (what is allowed and what is not),
- consistency (it applies equally to everyone),
- meaning (why it matters),
- and support (stress and desperation are fuel for fraud).
Concrete actions that reduce cheating attempts
- Explicit honor code (short and understandable).
- Honesty declaration before submitting (“I declare that this test reflects my own work…”).
- Prior training: what is plagiarism, what is improper collaboration, how to cite, what happens with AI.
- Clear policy on AI:
- If it is prohibited: say so, explain the scope, and align the exam design.
- If it is allowed: define how (for example, “it can be used to generate ideas, but you must cite prompts and justify decisions”).
- Real feedback: when students see that the assessment helps them improve, the system is perceived as more legitimate.

Multi-layer architecture: the combination that truly works
The most robust strategy is not a single “great” mechanism, but an architecture in layers that reinforce each other:
- Pedagogical Layer: questions that demand comprehension, transfer, justification, and application.
- Configuration Layer: randomization, large banks, reasonable time limits, adjusted navigation.
- Supervision Layer: proportional proctoring to the impact (authentication + environment + screen).
- Human Review Layer: analysis of incidents and evidence; do not automate critical decisions without review.
- Cultural Layer: clear rules, training, communication, and consistency.
When this is well put together, something interesting happens: cheating stops being worthwhile. Not because “students feel watched,” but because the exam is designed so that cheating is difficult, risky, and not very useful.
Realistic implementation roadmap in 5 months
Changing evaluation takes time. But it is possible to advance in stages without overwhelming the teaching team.
Month 1: quick audit of the current exam
- Classify questions: literal memory or application?
- Detect problematic items: ambiguous, trivial, repeated, leaked.
- Rewrite the 30% most fragile towards scenarios or justification.
Month 2: question bank + randomization
- Move from a “fixed list” to a bank by topics.
- Activate randomization of order and options.
- Pilot with a small group to detect configuration failures.
Month 3: introduce at least one authentic task
- A brief applied case, a mini-project, or a 3–5 minute video defense.
- Design a simple rubric (3–5 criteria, 4 levels).
Month 4: decide if you need proctoring (and under what conditions)
- Define risk levels (low/medium/high).
- If the exam is high-stakes, evaluate solutions with integration into your LMS (e.g., Moodle) and review legal compliance and user experience.
- Create a “practice exam” for the students to familiarize themselves with the system.
Month 5: communication and culture
- Publish integrity rules + AI policy.
- Explain the why of the changes.
- Adjust the exam with feedback (teachers and students).
Final checklist (useful if you have to set up an exam tomorrow)
Before the Exam
- Clear learning objectives aligned with questions.
- Sufficient question bank (and growing).
- Questions with application/justification (not just definitions).
- Randomization activated (questions and options).
- Rubrics ready if there are open questions or cases.
- Clear policy on AI, collaboration, allowed materials.
- Contingency plan for technical problems.
During
- Reasonable time (and active accommodations if applicable).
- Navigation configured according to impact (with prior practice).
- Proportional supervision (if applicable).
After
- Review of questions with unusual failure/success rates.
- Incident log (technical vs. behavioral).
- Useful feedback for learning.
- Update the bank: improve or remove weak items.
Conclusion
Designing more reliable and secure exams isn’t about ‘pressuring’ the student; it’s about making the assessment a credible reflection of learning.
When questions demand real thought, when the technical configuration reduces obvious opportunities for fraud, when supervision is used proportionally, and when the institution cultivates integrity with consistency, fraud becomes – to a large extent – unnecessary.
Evaluation in the digital age does not have to be an infinite game of cat and mouse.It can be a modern, fair, and rigorous practice that rewards what is important: understanding, applying, arguing, and building knowledge.